outricher/intro
AI search engine & AI data analyst · over a global base of people and companies
Describe who you need in one sentence. Get a scored, contact-ready list the same day.
AI search across one of the world's most complete bases of people and companies — we find anyone, on queries of any complexity. Not a raw list: a curated, ranked slice of exactly the people you asked for, every row with the evidence for why it is there. Through our analyst, or through the API inside your own systems.
data fields per contact — personal emails, phones, socials, the whole career
profiles already enriched with personal emails, phones and social handles
average data freshness; the top segment refreshes daily, nothing older than 90 days
per contact for full data through the API, refreshed live at request time
Global coverage of professional profiles · AI consultants and human operators on call 24/7 · a free trial set before you pay for anything.
What you are stuck on
Start from the problem, not from a filter panel
Most people come to us with one of these. Each row is what the problem looks like, what we actually do about it, and what it has produced for clients.
Sales & SDR
“Our cold outreach gets 1–2% replies — every email reads like a template.”
We pick people at the moment they are likely to buy — a fresh round, an open role in your function, a new job in the last 90 days — and reach them at a personal email, past the corporate filter. 130+ fields per lead give the model real material to personalise with. Outricher plus an LLM plus a sender is, in effect, an autonomous SDR.
replies, against 1–2% for generic lists
Sales · timing
“We sell to teams that don't have the role yet — no tool can search for an absence.”
Negative search: companies with no VP Sales, no HubSpot, no posts for three months. Combined with funding and open roles, it finds the buying moment others can't query — for example, funded companies that hired an SDR but have no sales leader.
revenue against data cost in one quarter; 14 deals closed from the pilot
Recruiting
“InMails get ignored, and a résumé doesn't show whether the person really ships code.”
We read skill from public code — 204M developer profiles — and from the full career, not from self-description. Candidates come with a personal email, so the message lands outside the job board, where passive people actually read.
reply rate, against 10–15% for InMail
Recruiting · hard-to-find talent
“We need a narrow profile — ML, a specific stack, a specific school — and the pool looks empty.”
Career history over 5.6 billion positions, education cross-checked against thousands of universities, geo resolved at the person level. Queries like «ex-fintech backend engineer near Tbilisi» are one request, not a week of sourcing.
hires in one quarter for an AI/ML team, from 8,000 validated candidates
Founders
“We need investors who actually back our space, and our first customers.”
Investors found by the deals they made into companies like yours, with the partner still in post and a personal contact. Decision-makers for first sales; a co-founder who is between projects right now.
every investor tied to a dated round in your direction
Investors & strategy
“We learn about a team's moves when they're already news.”
Put companies and people on watch: role changes, a new round, a burst of hiring, three senior engineers leaving at once. Talent tracking, portfolio monitoring and competitive maps from the same data.
a notification when something changes
Ops & RevOps
“Data we buy goes stale, and it lives in a spreadsheet instead of our CRM.”
An enrichment API: an email, a profile link, a phone or a handle in, a full dossier back in 1–2 seconds, refreshed live. It also works the other way — a plain-language description in, ranked people out. We wire it into your CRM, outreach tool or n8n / Pipedream.
per dossier; average freshness ~3 days
Marketing & research
“We need a picture of a market or an audience, not another list.”
The same engine writes finished research: market maps, talent flows, audience portraits, with the contact files behind every chart. Work consulting firms bill in weeks, usually within a day.
from one sentence to a report with segments — see public studies
The tool
AI search engine + AI data analyst
Many companies have raw data now. What is scarce is the tool on top of it — and a tool is useless without depth. We have both: coverage is the floor; what we sell is the research layer above it.
AI search engine
One sentence in — a selection out
Ask for any group of people or companies with the parameters you need. The agent asks what's unclear and proposes a brief based on what is actually in the database, not on what a filter panel happens to offer.
AI data analyst
Scores, segments, a report
In the same chat it scores the results against your ICP, surfaces the hottest leads and decision-makers, builds segments, runs the analysis and assembles the report.
Requests people actually send
All filters combine. You get either a focused set of the hottest decision-makers or everyone who matches — every contact with the evidence for why it made the list. Through an operator (a scored file in 24–48 h) or through the API (a plain-language request in, JSON with ranked contacts out).
What you can collect
Moments of need, not job titles
A title tells you who someone is. These tell you who is ready to talk this month.
Companies that started hiring for your function — each with the hiring manager's personal email
Startups with fresh funding, looking for contractors, tools and partners right now
People who use your competitor's product — identified by skills, experience and role description
Every decision-maker at a target company, for multi-threaded selling or partnerships
Specialists in their first 90 days in a new role — the most open to new tools and offers
Candidates who recently updated their profile — a signal they're ready to move
Companies and people that just appeared — you reach them before competitors do
Depth
Five things a catalogue architecturally can't hand you
Not «yet another data aggregator»: our own index over one of the largest profile datasets in the world, with joins across sources that catalogues keep in separate tables. Five techniques you won't find in Apollo, ZoomInfo or Sales Navigator.
Cross-signal triggers
Combine signals that don't work on their own
«Funded companies that hired an SDR but have no VP Sales yet» is a buying trigger at the intersection of three independent sources: funding rounds, job postings and the current org chart. Aggregators store these separately and can't join them.
→ real case: 1,479 leaders · 86% with email
target: companies
where:
  funding_round in [seed, series_a]
  funding_recency: 6 months
  has_open_role: SDR | BDR
  no_employee_with_title: VP Sales
→ 1,479 leaders · 86% emails
Negative search
Search by what is not there
«Companies with no HubSpot», «teams with no VP Sales», «profiles with no posts for three months». Others filter by the presence of a trait; we filter by its absence — a different operation that catalogues haven't built.
→ 3–4× less noise in outreach vs positive-only filters
target: people
where:
  title contains 'Engineer'
  experience > 5 years
  company.has_title: NOT 'VP Engineering'
→ 3,847 senior ICs to recruit
Career history · 5.6B positions
Search by who a person used to be
«Ex-SpaceX, now investing in AI», «ex-Stripe at funded startups», «YC 2020–2022 alumni, now CTO». A join over 5.6 billion positions — the filter runs on a specific past-and-present pair.
→ up to 100% match precision
target: people
where:
  past_companies includes [SpaceX, Tesla]
  current_company.industry: 'venture-capital'
→ 287 ex-rocket engineers turned investors
Bulk + scoring
10,000 contacts in one export — already scored and segmented
Sales Navigator gives 2,500 a month as a raw list; Apollo, small batches through the interface. We deliver 10,000+ contacts in one export, sorted by score for your ICP and split into ready segments.
→ ready for outreach, not raw fields
delivery/
├─ leads.xlsx      multi-sheet
├─ leads.csv       CRM import
├─ segments/
│  ├─ hot.csv      score 25+, email
│  └─ founders.csv · hiring.csv
└─ README.md       metrics
Up to 130 fields per profile
Full context, not just an email and a title
Contacts (an email waterfall, phone, GitHub, X), the current role and full history, education, skills, recommendations, a salary estimate, profile activity, company size, funding and hiring status — up to 130 fields per person.
→ 50 fields in a free sample · up to 130 after full enrichment
profile:
  contacts: email · phone · socials
  career:   5–13 positions
  company:  size · funding · hiring
  code:     GitHub repos & activity
→ one stitched object, 130+ fields
Proof
What it did for clients
Reply and conversion rates our clients reported, against the baseline they had before. Ranges are ranges across campaigns; names are disclosed only with permission.
Hiring · filtered by real code
Adobe — data engineers by open-source activity
2,088 candidates out of 145K developers
Java / Scala / C++ engineers with live open-source activity, including 11 Apache contributors (Flink, Spark, Trino, Iceberg), scored into tiers so the team could start with the top band. Read the case →
Sales · the 60–90 days after a round
B2B SaaS — founders of funded startups
11% meeting conversion · baseline 1–2%
8,597 contacts at 2,390 companies · 79% with email in the top 3,000 · 77% actively hiring · 8 segments. Outreach went to founders' personal email. The contract became recurring.
Sales · negative search
Series A/B — search by the absence of a role
~40× revenue against data cost, one quarter
A request Apollo and ZoomInfo can't run: «companies where the role doesn't exist yet». 1,479 leaders at 747 companies · 86% with email. Pilot: 8% replies against a 2% baseline; 14 deals closed.
Recruiting · education cross-check
AI/ML recruiting — visa-friendly talent
23 hires in a quarter
8,000 validated candidates in 4 batches · ML engineers with 5–15 years of experience · education cross-checked against 7,650 US universities. Foreign-educated candidates converted to interviews about 30% better.
This is only part of it. Tell us your task — we like unpacking new cases. Telegram @outricher
Research desk
Consulting-grade reports in a day
Beyond exports, the same engine produces finished research — market maps, talent-flow studies, ecosystem and audience analyses — with charts, segments, conclusions and the contact files behind them. Below are public studies; most client research ships privately under NDA. Each one started as one sentence in a chat.
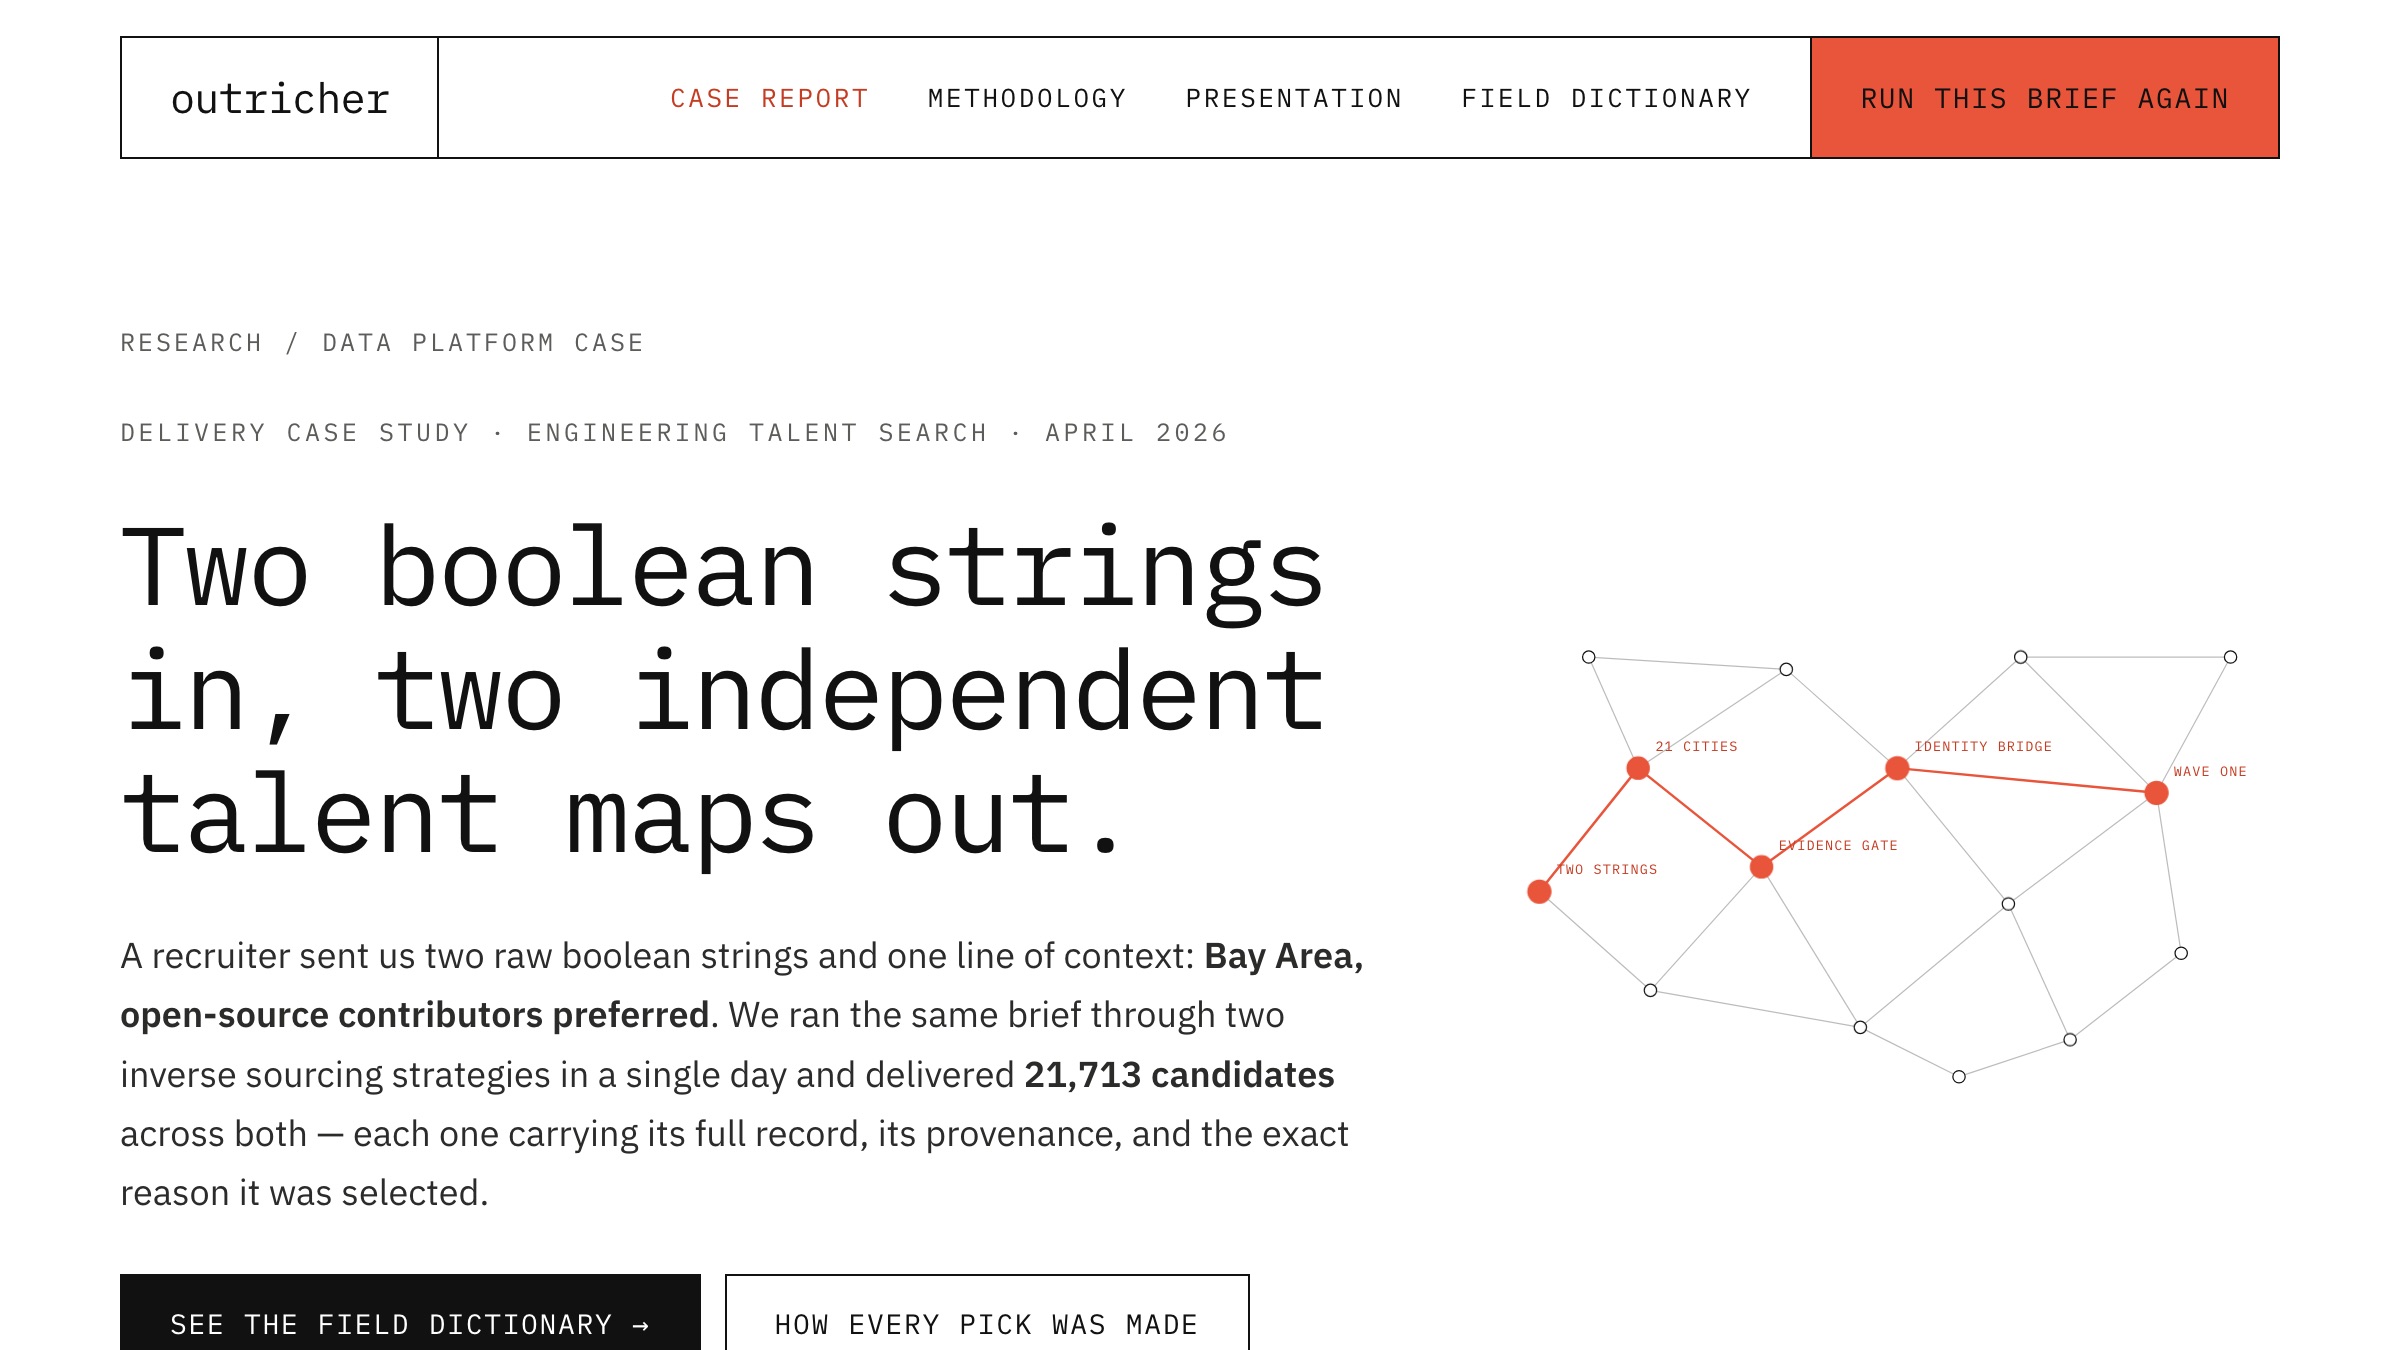
Delivery case
Two search strings, two talent maps
A recruiter sent two raw search strings. We ran them as two independent sourcing strategies in one day — 21,713 engineers, every pick traceable, the full field dictionary downloadable.
recruitingOpen →
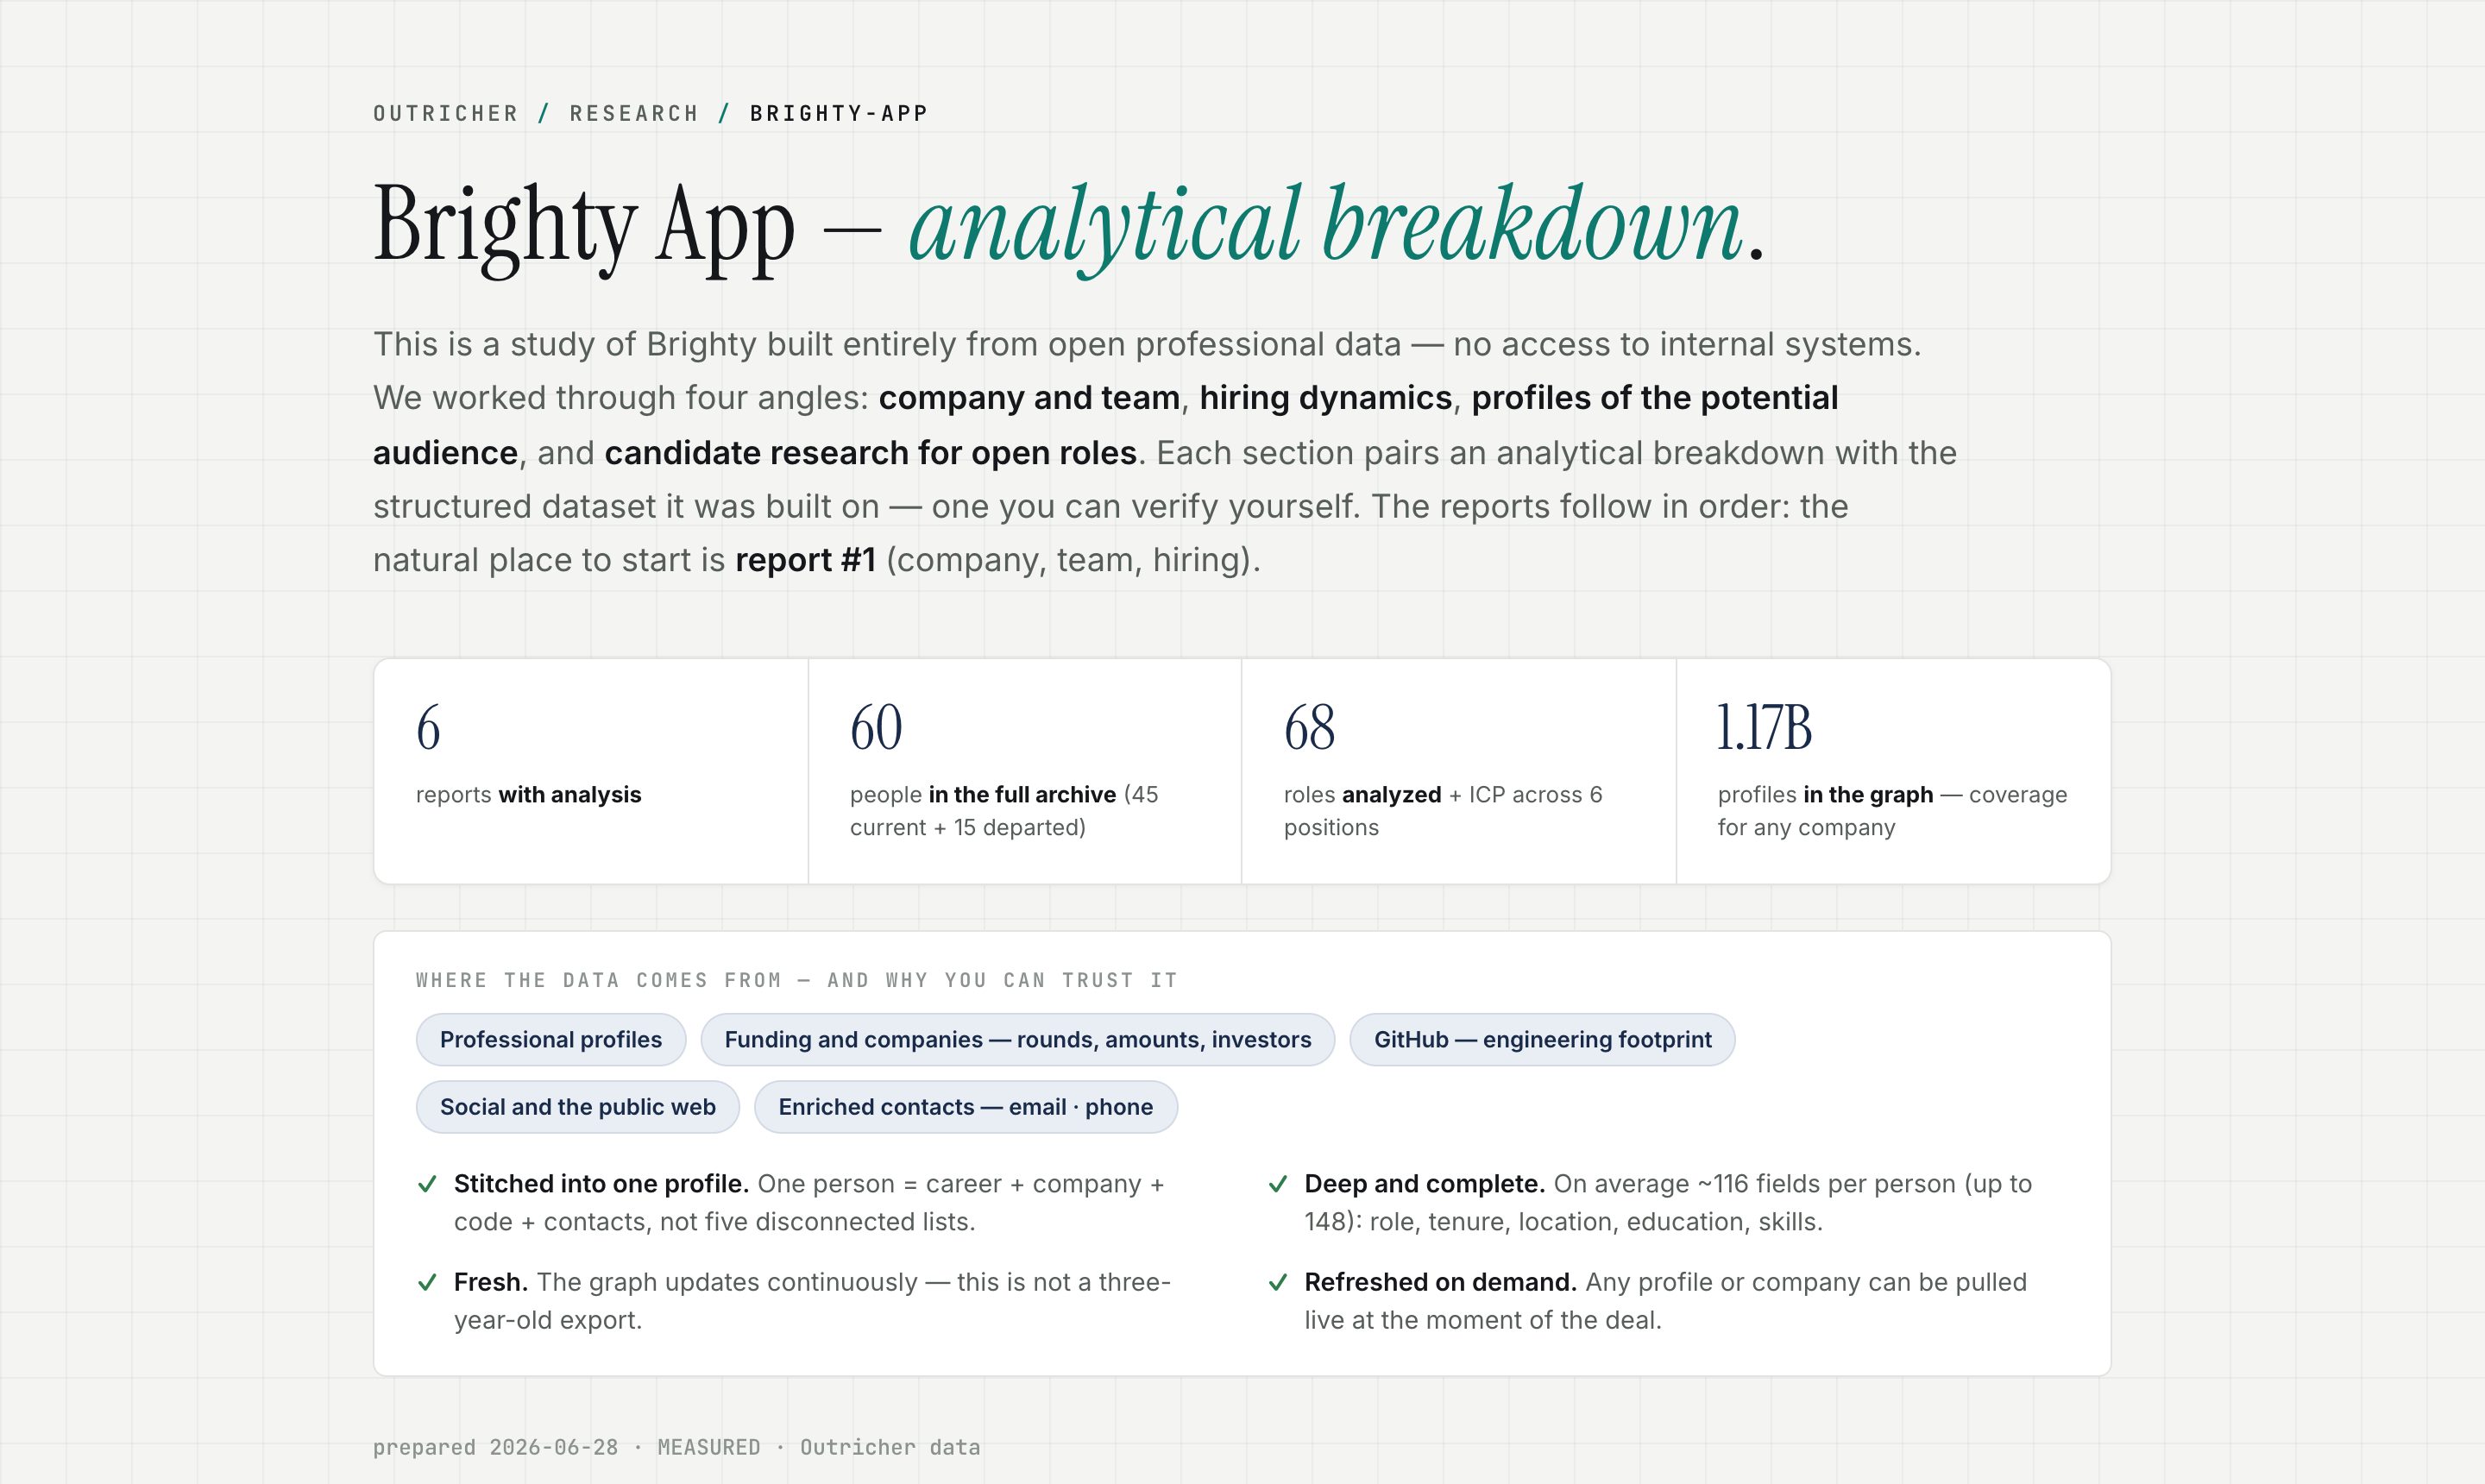
Client research
Brighty App — a full company breakdown
Six reports from open data only: company and team, hiring dynamics, eight audience portraits with ready contact segments, and the anatomy of a 130-field profile.
company studyOpen →
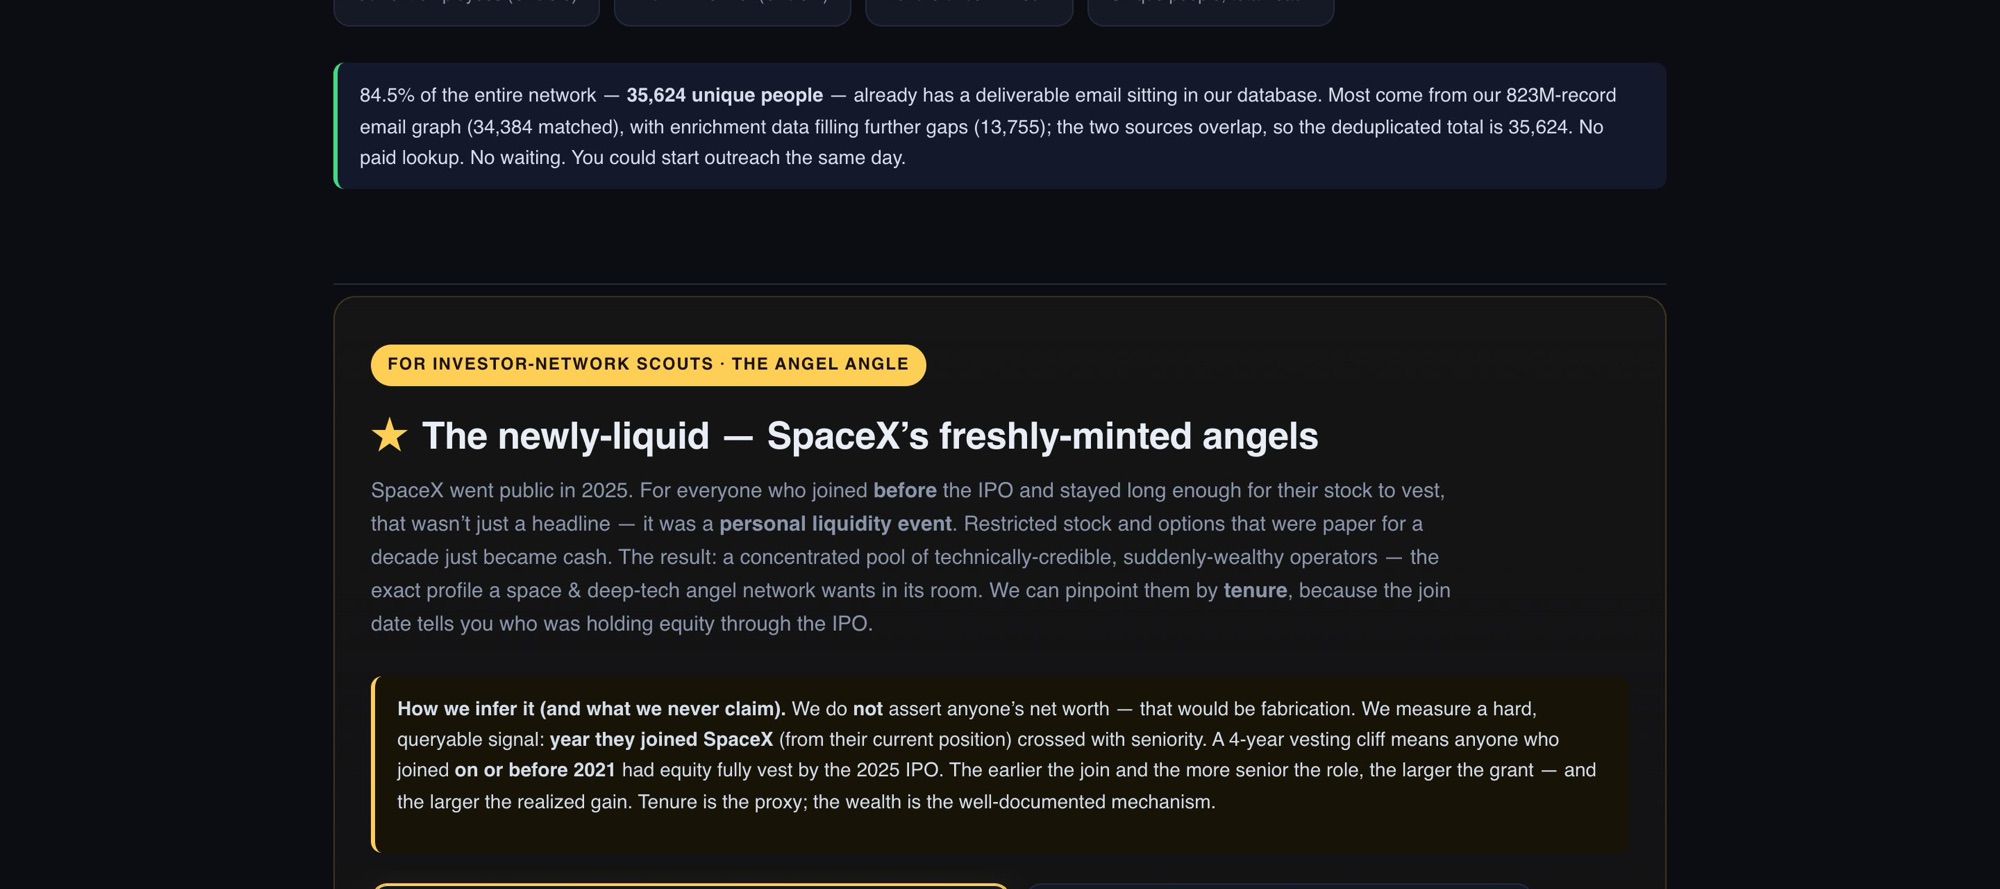
Ecosystem map
The SpaceX alumni ecosystem
One company's alumni traced through career history: who left, when, what they founded and who backs them. A targeting map for investors and recruiters.
career graphOpen →
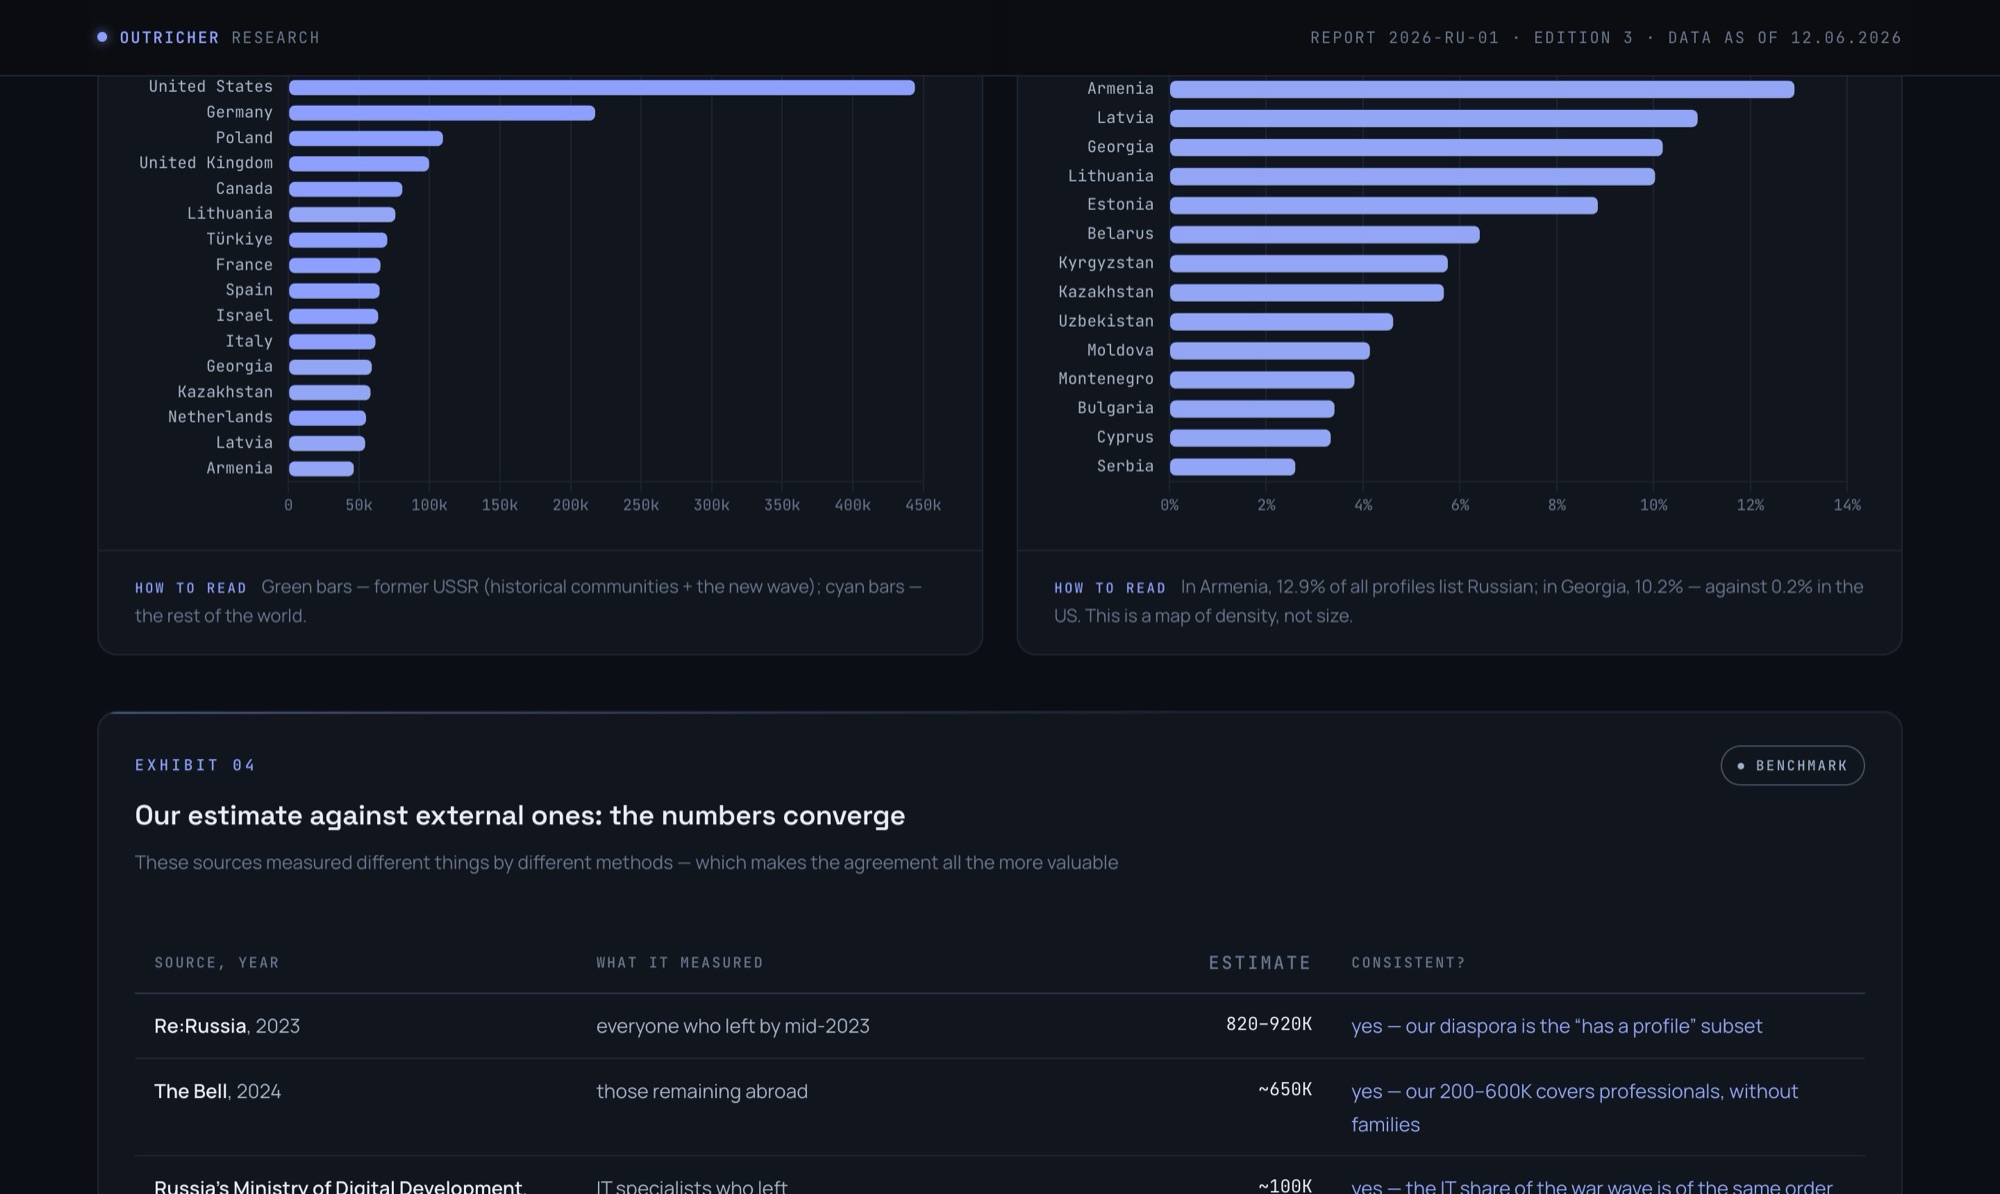
Talent flows
The Russian-speaking tech exodus
A population-scale migration study from profile data alone: which hubs absorbed the engineers, the seniority and stack mix, and where density is high enough to hire or sell into.
migrationOpen →
Workforce economics
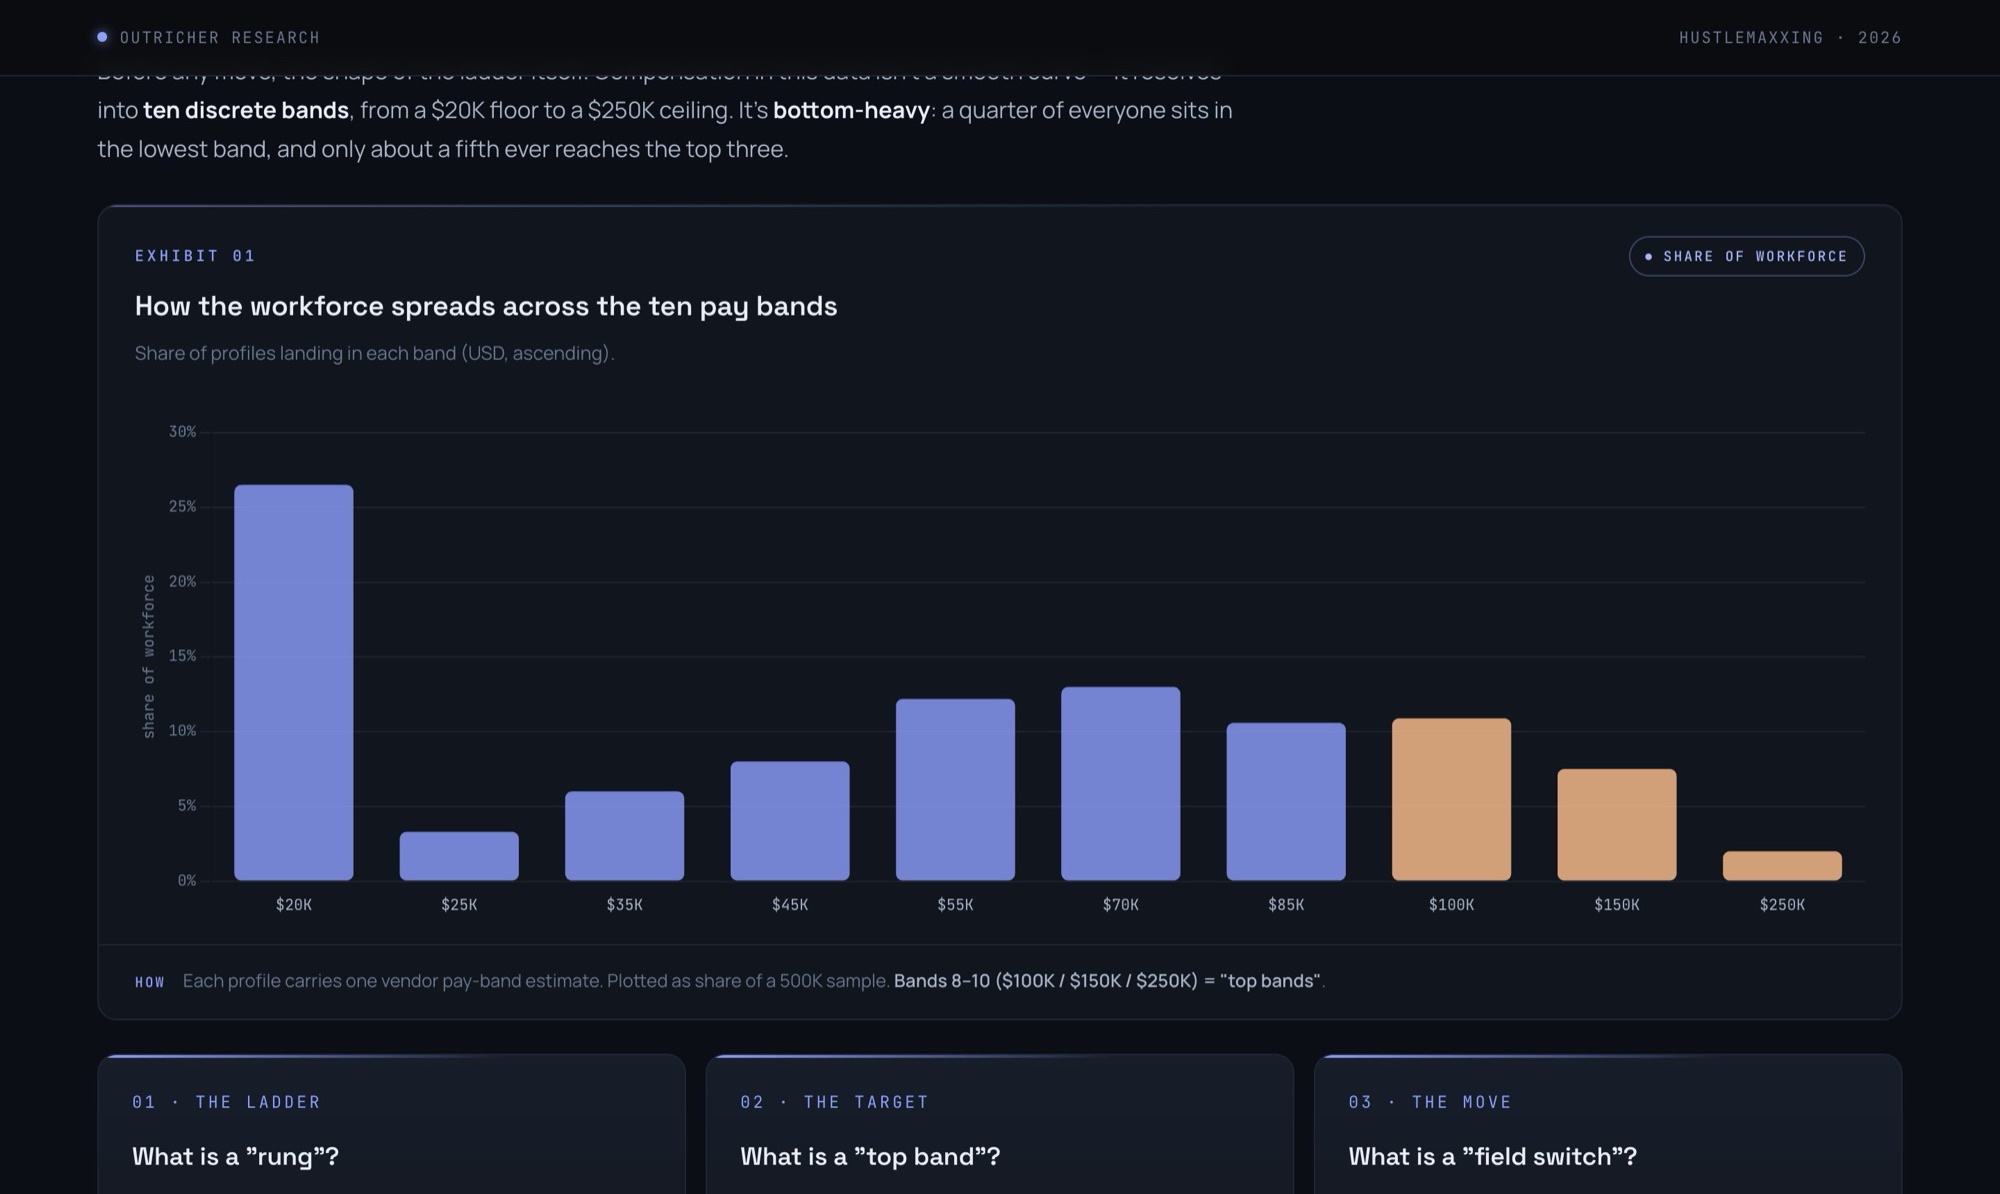
Hustlemaxxing — the multi-job economy
How the workforce spreads across ten pay bands and where people quietly stack several roles at once — compensation analytics no salary survey can see.
compensationOpen →
Market scan
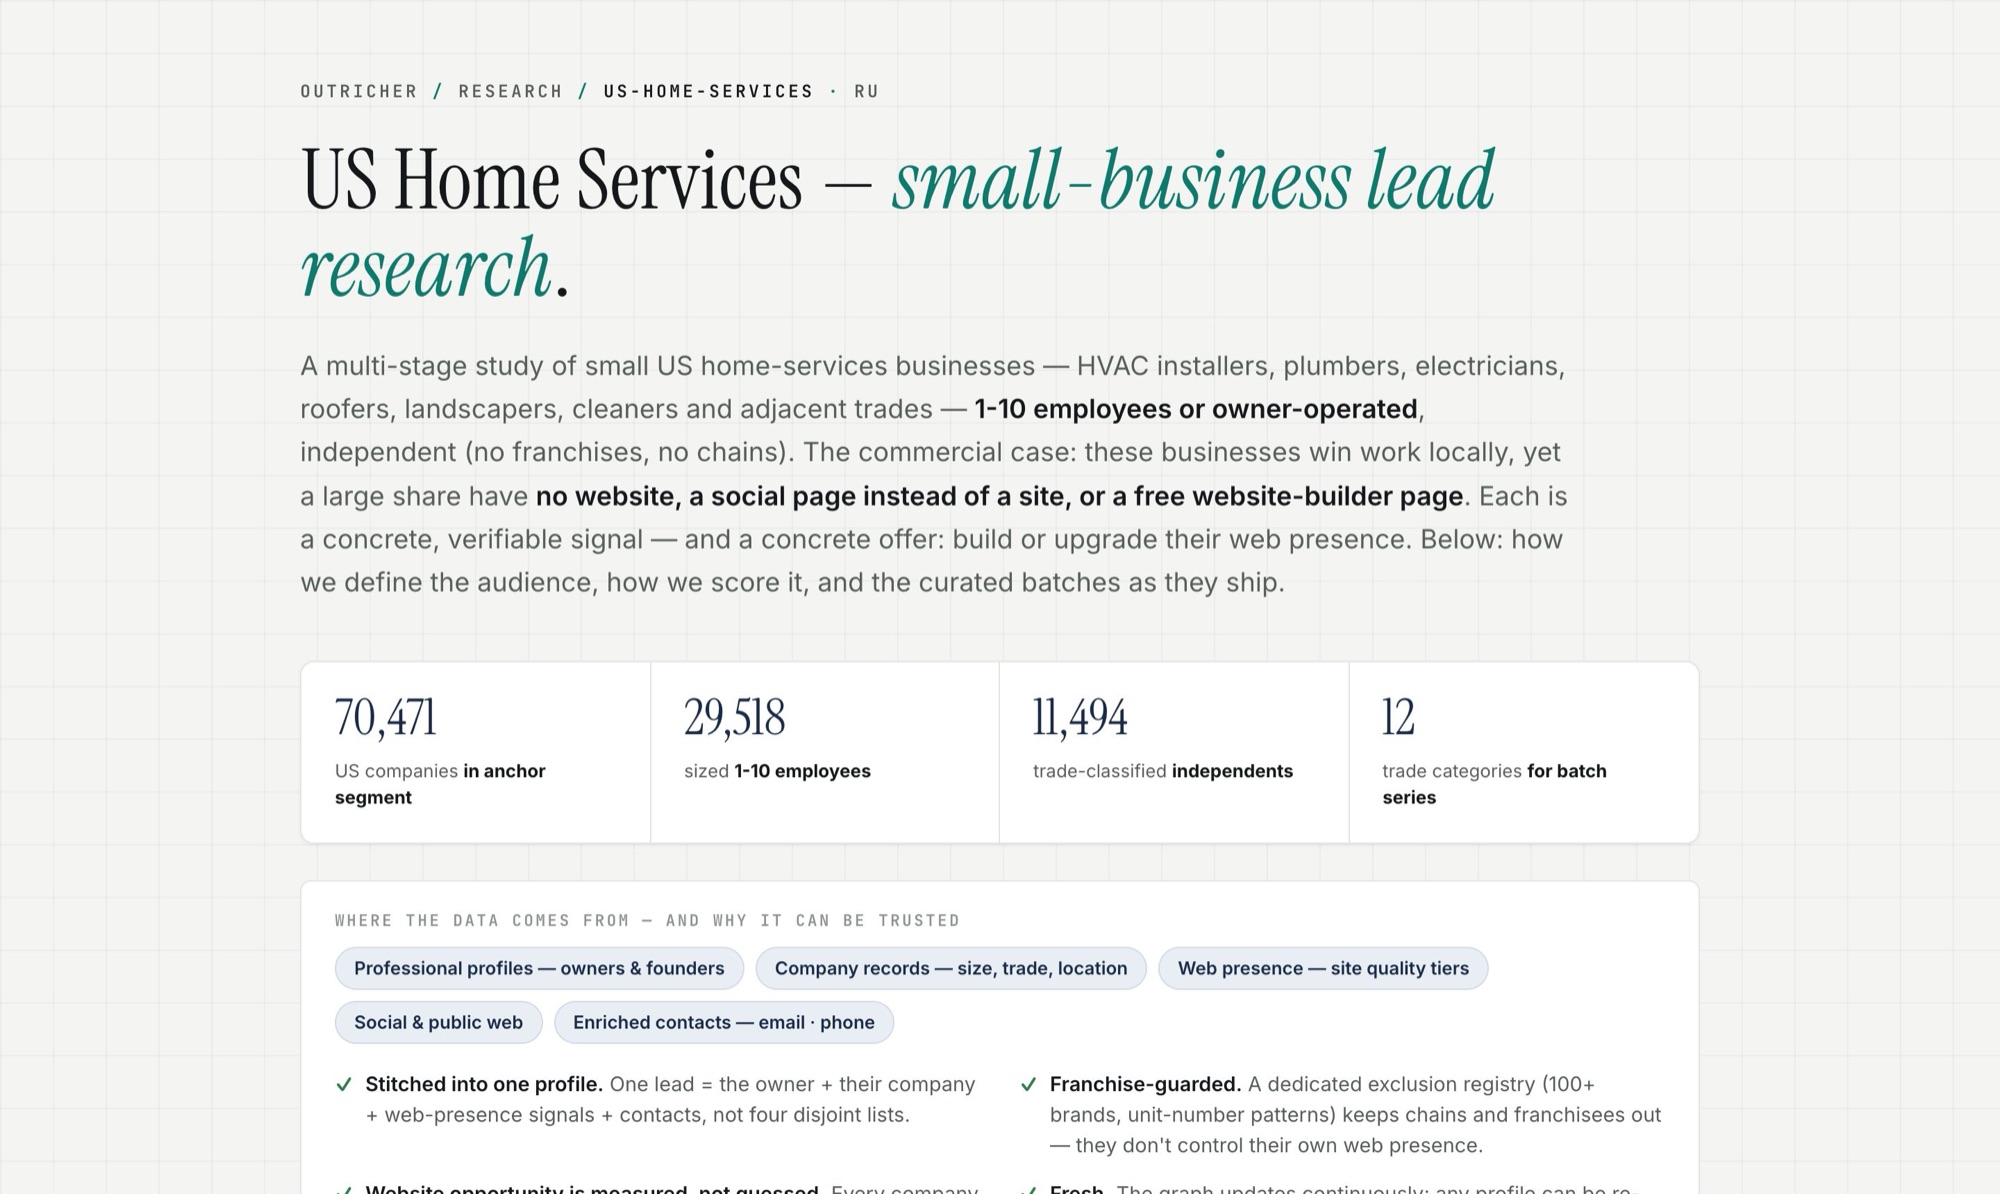
US home services — an outreach-ready market
Thousands of US home-services businesses scored by digital gaps — no booking, weak web presence, room to sell into. A report that doubles as a lead pool.
market mapOpen →
Targeting engine
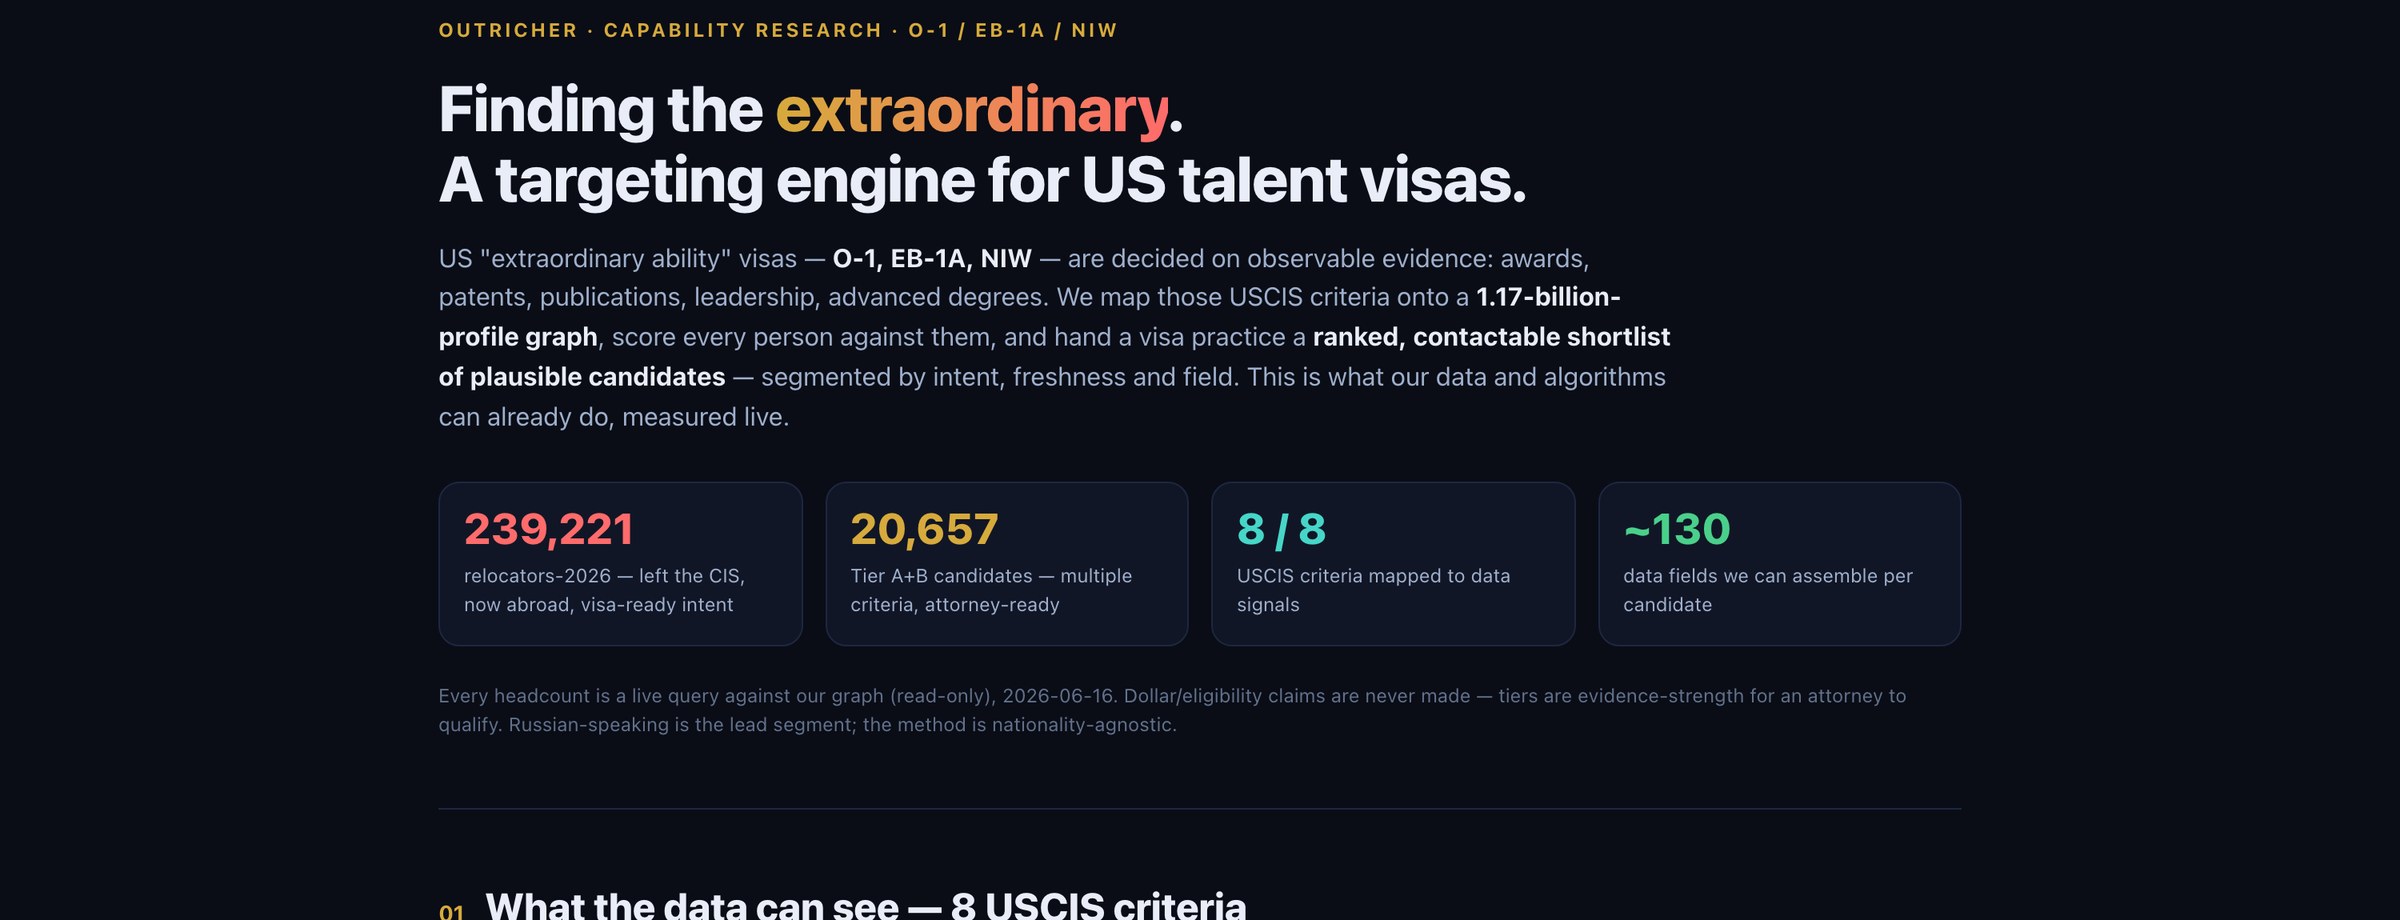
Finding the extraordinary — US talent visas
The eight USCIS criteria for O-1, EB-1A and NIW mapped onto profile data, scored across the whole graph and turned into a shortlist an immigration practice can work.
scoringOpen →
Library
All public research
Every study we have published, in one place, with the method behind each one.
outricher.com/researchOpen →
How to start
Three steps, and the first two are free
Describe the task
Who you are looking for, in your own words — a single message in the form below or on Telegram @outricher.
free · 5 minutes
Get a trial set
The agent clarifies the details and builds the brief. You get 20 contacts for your ICP to judge the fit yourself.
free · usually 1–2 hours
Scale or refine
If it fits, order the full export or connect the API. If it doesn't, we rebuild it for the refined request.
full export · 24–48 hours
Step zero
Free consultation
20–30 minutes: together with our AI agent we unpack your situation and show which data and signal combinations will actually help.
Hands-on
Turnkey integration
Connecting to your CRM, outreach tool, n8n or Pipedream; trigger signals and scoring set up for your ICP.
Ongoing
A recurring pipeline
Regular refreshed exports, with feedback on data quality and outreach conversion. Most clients arrive with one task and leave with three.
Market
How we compare
The main difference isn't price, it's depth and the tool: one plain-language request returns data joined from several sources and checked. For a sense of cost and coverage:
| Metric | Outricher | Apollo | ZoomInfo | Lusha | Clearbit |
|---|---|---|---|---|---|
| Price per contact | ~$0.09 | $0.15 | $2.00 | $0.12 | $0.71 |
| Database size | largest on the market | 275M | 260M | 150M | 400M |
| Career history | 5–13 positions | 2–3 | 2–3 | current | current |
| Developer (GitHub) data | 204M | — | — | — | — |
| Personal emails | 237M, included | paid | paid | paid | — |
| Freshness | daily / weekly | monthly | quarterly | unknown | no SLA |
| Plain-language AI search | yes | filters only | filters only | — | — |
| Custom exports | 24–48 h for your task | self-serve | self-serve | — | — |
Apollo and ZoomInfo are good self-serve filtering tools. Outricher solves a different problem: you describe the case and we engineer the data for it, with depth — full career, code, funding, hiring — that ready-made catalogues don't have.
Under the hood
The data, in full
Everything above rests on one database. This is the detail for those who want it — you don't need it to start; just describe your task.
One dataset
Stitched, not collapsed
Company profiles, hundreds of millions of ready contacts, full career history, developer profiles, job postings and education records — one dataset, sources cross-checked.
Monitoring
Watch lists
Role change, a new round, an open vacancy, an activity spike — a notification when something changes. Triggers combine for your ICP.
Enrichment API
A dossier in 1–2 s
An email, profile link, phone or handle in, a full dossier back. Both directions: contact → profile, and description → people.
Price
~$0.09 per contact
Full data through the API with a live refresh at request time. The exact cost depends on enrichment depth and volume.
The object
What you get in a profile
The unit of data is a stitched profile: one person = identity + contacts + full career + current company + education + skills + public code, linked into one object of 130+ fields. The same object answers sales, recruiting and research questions at once.
Person
Identity & contacts4 groups
Career & experience3 groups
Education & developer profile5 groups
Location, activity & extended profile7 groups
Company
Basics, structure & relationships6 groups
Funding & hiring7 groups · unique
Which fields matter to whom
| Task | What carries it |
|---|---|
| Sales | Role + company + headcount + geo + email. Timing signal: the start date in the role — the first 90 days is when new tools get evaluated. |
| Recruiting | Career history + education + skills + contacts. «Ex-fintech backend engineer near Tbilisi» is one query — past employer, geo and role live in a single object. |
| Investing & research | Company + headcount + founding year + hiring. A two-year-old company opening 10+ roles is a growth signal no business directory shows. |
| Marketing & ABM | Headline + industry + geo + activity. The headline is the person's own one-line pitch — personalisation written by the recipient. |
A live example
One real, complete object from an API pull — a fractional CTO in London, 114 fields. Contact values are masked on this public page. Base fields, db_* and api_* layers are independent and never collapsed, which is why the union passes 130.
profile.json — open the full object114 fields · masked
{
  "profile_id": 10153971,
  "full_name": "Alfonso F.",
  "headline": "The Restless CTO · AI Evangelist · Co-founder · Educator · Advisor · Fractional CTO",
  "title": "Fractional CTO",
  "function": "consulting_strategy",
  "role_bucket": "c_level",
  "seniority_tier": "A",
  "years_experience": 25,
  "company_employee_count": 38,
  "current_positions_count": 8,
  "location_name": "Greater London, England, United Kingdom",
  "email": "a•••••••@•••••••.com",
  "all_emails": ["a•••••••@gmail.com", "a•••••••@•••••••.com", "a•••••@•••••••.co.uk"],
  "personal_phone_numbers": ["+4478•••••928"],
  "github_url": "github.com/•••••",
  "twitter_url": "x.com/•••••",
  "skills": ["Leadership", "Software Design", "C#", ".NET", "JavaScript", "SQL", …],
  "db_experiences": [
    { "title": "Software Architect", "start_year": 2006, "end_year": 2008 },
    { "title": "Software Developer", "start_year": 2001 },
    { "title": "Technology Adviser", "start_year": 2023, "is_current": true },
    { "title": "Professor — AI Executive Master", "start_year": 2021 }
  ],
  "db_education": [{ "degree": "PhD", "field_of_study": "Computational BioFluid Dynamics" }],
  "between_jobs": false,
  "signals": ["signal_fractional", "signal_advisor", "signal_portfolio_career"],
  "score_details": ["signal_fractional:+30", "signal_advisor:+18", "seniority_a_founder_clevel:+20", "has_email:+3"],
  "lead_score": 99,
  "lead_label": "A+",
  "outreach_ready": true,
  "api_connectionsCount": 4496,
  "api_followersCount": 6362,
  "api_seniority": { "totalExperienceYears": 24, "currentTenureYears": 12 },
  "salary_min": 150000,
  "salary_max": 250000,
  "db_profile_activity_at": "2026-03-05T13:26:40Z",
  "…": "114 fields in this object; the full schema is in the docs"
}
Sources & compliance
Only what people made public themselves
All data lives in Outricher's own database, continuously integrated and refreshed against the freshest datasets in the industry, with every licence required for commercial use. We operate in line with GDPR / CCPA, every delivery has an audit trail, and a DPA is available on request. No closed or breached sources.
Start here
Tell us who you need. We send 20 of them, free.
One or two sentences are enough — who, where, and what should make them a fit. We reply within one working day with questions or a trial set; documentation, JSON examples and an AI-tool demo on request.